The Google Indexing API only supports job postings and livestreams. Here is what actually gets thousands of product pages indexed instead.
Table of Contents(6 sections)
What the Indexing API actually does
Google's documentation is not ambiguous about this. In its own words: "The Indexing API can only be used to crawl pages with either JobPosting or BroadcastEvent embedded in a VideoObject."
That is the whole permitted surface. Job posting pages, and livestream event pages. Not product pages, not category pages, not blog posts. The API exists because those two content types expire — a job closes, a stream ends — and Google wanted a way to be told quickly rather than waiting for a recrawl.
The default quota is 200 publish requests per day, per project. That number is the source of most of the confusion: it looks like a rate limit to be engineered around, when it is really a limit on a feature that was never meant for your catalogue.
Why the multi-account trick is a bad trade
The "rotator" approach — several service accounts, requests spread across them — is not a clever workaround. It is the specific behaviour Google's documentation calls out:
Don't circumvent our submission limits, such as by using multiple accounts.
And, on the same page:
Our spam policies apply to content submitted with the Indexing API.
So the trade is: you spend real engineering time building something that, at best, submits URLs Google has said this endpoint does not crawl — and at worst puts your project's API access and your site's standing at risk. There is no version of that trade that pays.
This matters more in 2026 than it did a few years ago. Google has confirmed three spam updates this year, in March, June and August. If you are going to spend a week on indexing work, spend it on something that cannot be read as circumvention.
Why the myth is so persistent
Because people try it and their pages get indexed, so the API gets the credit.
In practice, nobody runs an indexing script in isolation. The same week, they also submit a sitemap, fix a broken canonical, add internal links from a category page, or prune a few thousand thin URLs that were eating crawl budget. Pages then get indexed — and the most novel-looking thing in that list takes the credit.
If you want to know whether the API did anything, you would have to run it with no other changes, on a site with no other movement. We have never seen that test done, and we would not spend a client's month on running it.
CUSTOM SEO DIAGNOSTIC · TECHNICAL SEO
How Does "The Google Indexing API Is Not a Shortcut" Apply to Your Website?
Send me your URL and I'll check your site personally against what you just read — technical bottlenecks, competitor gaps, and whether Google's AI names you or them. Free reply within 24 hours.
What actually gets pages indexed at scale
Indexing is not a queue you can jump. It is a judgement Google makes about whether a page is worth storing. The work is making that judgement easy:
- Fix the reason Google declined. Open Search Console's Pages report and read the actual reason. "Crawled — currently not indexed" and "Discovered — currently not indexed" mean different things and need different fixes. Most large stores find near-identical boilerplate across thousands of SKUs, which is a content problem no API can solve. See Product Page SEO at Scale.
- Stop wasting the crawl you already get. Faceted URLs, session parameters and internal search results routinely consume most of a large site's crawl budget. Our crawl budget guide covers the audit.
- Submit clean XML sitemaps, split logically, containing only canonical, indexable, 200-status URLs. A sitemap full of redirects and noindexed pages teaches Google to trust it less.
- Link to the pages internally. An orphan page with no internal links is rarely crawled, whatever you submit. This is the highest-leverage and most-skipped step.
- Use URL Inspection for genuinely urgent pages. It is meant for a handful of important URLs, not a catalogue — but for those few, it is the supported route.
- Then wait, and re-measure in batches. Indexing at scale moves over weeks. Changing five things at once means you will never know which one worked.
What that looked like on a 35,000-page store
SMK Store had over 35,000 product pages that were barely indexed. The cause was not submission volume — it was thin, near-identical boilerplate descriptions tripping duplicate-content filters, plus failing Core Web Vitals.
We rewrote product content brand by brand, optimised crawl budget, implemented product schema, fixed Core Web Vitals, and resubmitted in batches through Search Console. Monthly net sales went from $5,832 in April 2026 to $19,100 in June 2026 (+227%) with no additional ad spend, as shown on the store's WooCommerce dashboard. The full write-up is in the SMK Store case study.
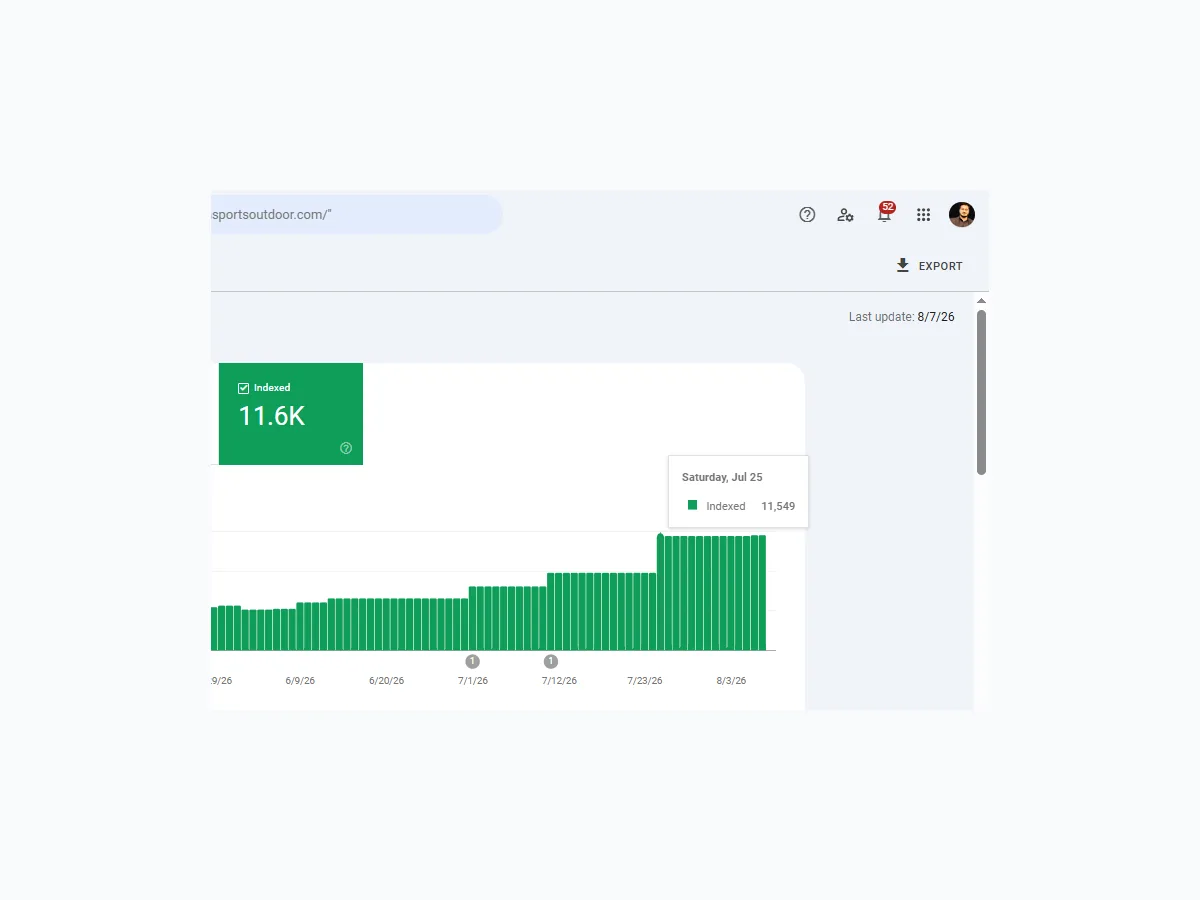
The honest version of a second project is worth including too. Michigan Outdoor Sports peaked at +476% organic clicks in March 2026, then lost ground to a gradual de-indexing before we rebuilt it to 11,549 indexed pages and +83% US organic clicks by July. Indexing is not a one-time unlock, and anyone selling it as one is overselling.
Do this week
- Export the Pages report from Search Console and group the exclusion reasons by count. That list, not a script, tells you what to fix.
- Pick the largest group and fix its root cause on a sample of 200 pages.
- Re-measure in three weeks before touching anything else.
- If you have a rotator script in production, retire it. It is buying you nothing and risking API access.
Sources
Mubashar leads SearchPrex’s founder-led SEO work for law firms, local businesses and ecommerce brands. He combines technical audits, Search Console data and local market research to build practical search strategies, with more than five years of hands-on experience across 20+ clients.
Join the Discussion or Request Our Next Topic
Share your perspective in the public thread below, or tell us what SEO teardown, case study, or update regarding The Google Indexing API Is Not a Shortcut you want us to cover next.
Community Perspectives (0)
Loading discussion...